Protecting Tower Infrastructure From DDoS Attacks
Why WISP towers make attractive targets and how to mitigate volumetric and protocol attacks.
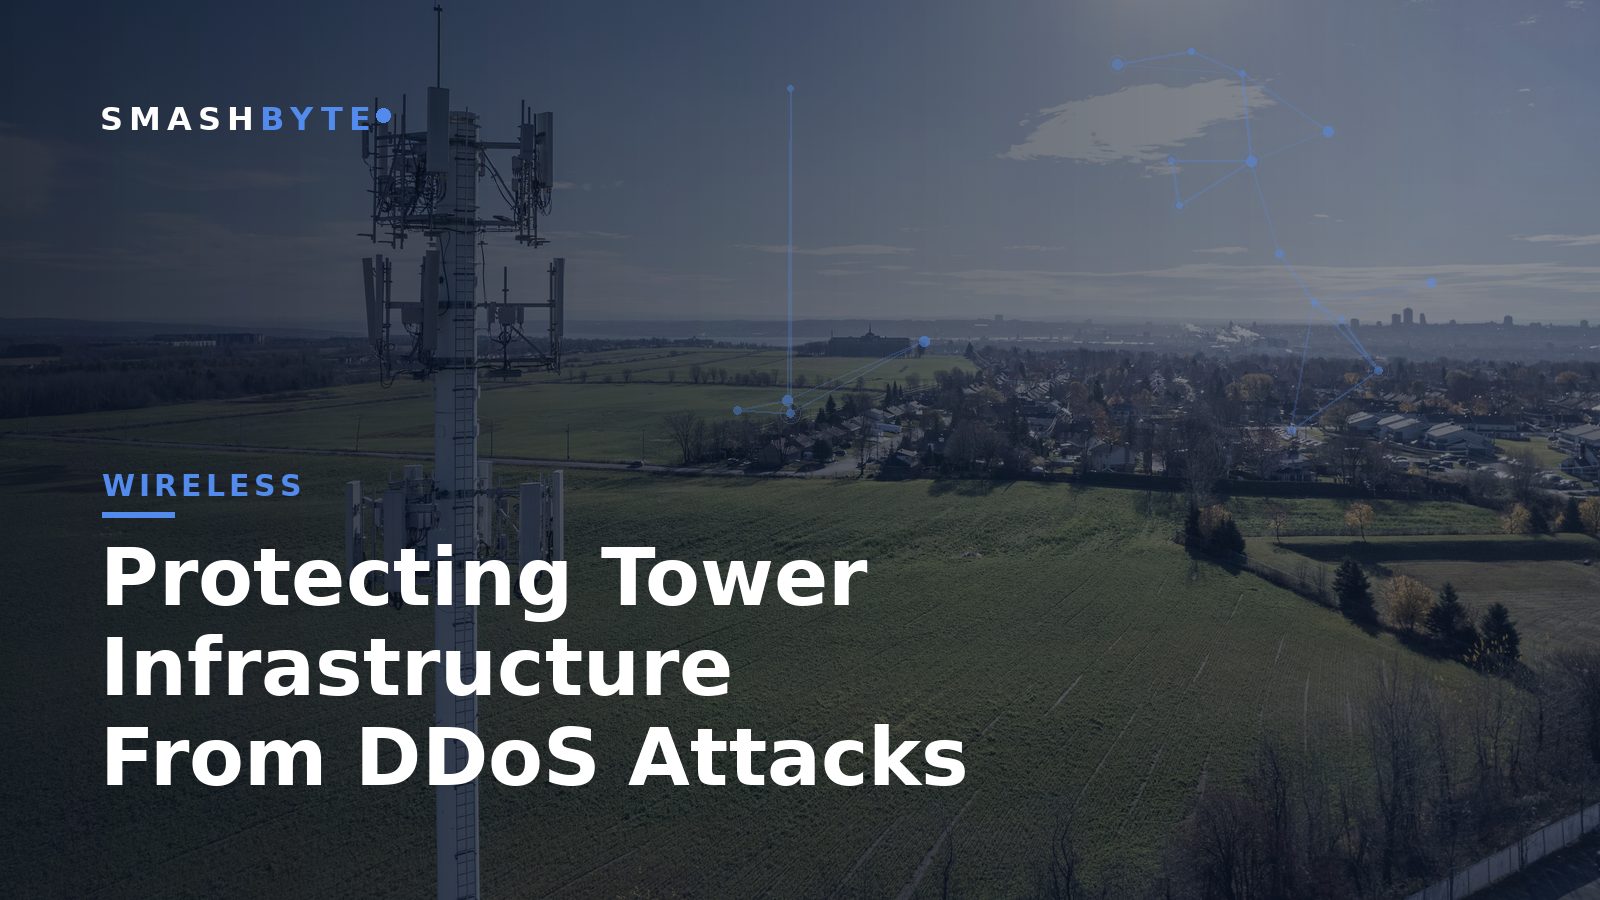
A DDoS attack does not need to target your tower directly to take it down. Enough junk traffic aimed at a single subscriber behind the tower can saturate the backhaul circuit, exhaust the tower router's resources, and degrade service for everyone on that sector. For WISPs, DDoS defense is less about exotic tooling and more about knowing where your chokepoints are and having a plan for each one.
This article explains why tower infrastructure is an attractive target, what attacks actually look like at a tower, and the layered mitigations — on-site, upstream, and architectural — that keep a bad afternoon from becoming a full outage. It pairs with our WISP tower cybersecurity checklist, which covers the broader security baseline.
Why WISP towers make attractive targets
Attackers do not need a grudge against you. Towers get hit for structural reasons that apply to almost every fixed-wireless operator:
- Concentrated downstream impact. One congested backhaul link or overwhelmed router affects every subscriber on the tower, so a modest attack produces outsized visible damage.
- Limited headroom. Many towers run backhaul circuits sized for normal peaks, not attack traffic. A volumetric flood that a large ISP would shrug off can fill a 1 Gbps tower circuit completely.
- Small routing tables and thin control planes. Tower routers are often commodity or mid-range devices whose CPUs are sized for forwarding, not for absorbing protocol attacks.
- Collateral targeting. Gaming disputes, extortion attempts and compromised-device botnets frequently target individual end users. Your subscriber is the target; your tower is the casualty.
- Remote, unattended sites. Nobody is standing next to the equipment to notice a problem early, so attacks run longer before anyone reacts.
The practical conclusion: assume attacks will happen, and engineer so that the most common ones are boring instead of catastrophic.
What attacks actually look like at a tower
DDoS is a family of techniques, not a single attack. The three categories below hit tower infrastructure in different ways, and each needs a different response.
Volumetric attacks
The attacker simply sends more traffic than a link can carry — UDP floods, DNS or NTP amplification, and similar techniques that leverage reflectors to multiply traffic volume. The bottleneck is pure bandwidth: your backhaul circuit, or your upstream provider's handoff to you. On-site filtering cannot fix a full pipe; the traffic has to be stopped upstream of the chokepoint.
Protocol and state-exhaustion attacks
TCP SYN floods and connection-table attacks consume state on routers and firewalls rather than bandwidth. A tower router that comfortably forwards its normal load can fall over tracking millions of half-open connections. These attacks can be small in Mbps and still deadly to an underpowered control plane.
Application-layer attacks
Targeted at services you host — a customer portal, DNS resolvers, voice infrastructure, or management interfaces that should never have been reachable in the first place. These are usually the lowest-volume attacks and the most preventable: most of them disappear entirely when management and service interfaces are properly isolated, as covered in securing routers at unattended tower sites.
Know your chokepoints before the attack does
Every tower has a short list of resources an attacker can exhaust. Map them now:
- Backhaul capacity. The circuit between the tower and your aggregation point. If this fills, nothing on-site matters.
- Router control-plane CPU. Routing updates, connection tracking and management traffic all compete for the same processor.
- Radio and sector capacity. Fixed-wireless sectors have finite airtime; downstream floods to subscribers consume it even when backhaul has headroom.
- State tables. NAT and firewall session tables have hard limits, and filling them breaks legitimate sessions indiscriminately.
Sizing backhaul with attack headroom in mind is a capacity-planning decision as much as a security one. The backhaul capacity calculator helps you model subscriber peaks; DDoS tolerance is the argument for not running circuits at the edge of that number during normal operation.
Baseline protections you control at the tower
None of these stop a large volumetric attack by themselves, but they raise the floor, shrink your exposure, and keep small attacks small. Most are configuration work you already have the hardware to do.
- Lock down the management plane. Management interfaces reachable only from a dedicated management VRF/VLAN or out-of-band path, never from subscriber space or the public Internet. This eliminates the most common application-layer attack surface outright.
- Control-plane protection (CoPP). Rate-limit traffic destined to the router itself — BGP, SNMP, ICMP, SSH — so protocol attacks cannot starve the CPU that keeps forwarding alive.
- Ingress and egress filtering. Drop obviously invalid traffic: bogons, spoofed source addresses from your own blocks arriving externally (uRPF where feasible), and outbound traffic with sources that are not yours. Egress filtering also keeps compromised CPE on your network from participating in attacks on others.
- Rate-limit risky services. Cap ICMP, UDP to unusual ports, and per-subscriber connection rates at the tower router so one customer cannot monopolize state tables or airtime.
- Secure your DNS resolvers. Run recursive resolvers for your subscribers only, never open to the world. Open resolvers on your address space make you an amplification source and a target.
- Pre-build emergency ACLs. Keep tested, documented filter templates ready to deploy in minutes — scrambling to write ACL syntax mid-incident is how outages stretch.
The broader hardening baseline — credentials, VLANs, out-of-band access, physical security — is in the tower cybersecurity checklist and the tower security solution overview.
Upstream mitigation: where volumetric attacks actually die
When the pipe is full, only someone upstream of the pipe can help. This makes your relationship with your transit and backhaul providers a security control, and it should be evaluated like one when you buy.
Remote-triggered black hole (RTBH)
The crudest effective tool: you announce the attacked destination prefix to your provider with a blackhole community, and they drop all traffic to it at their edge. The targeted address goes dark, but the rest of your network stays up. It requires a provider that supports blackhole communities and — on your side — BGP, which is one of the arguments in ASN and BGP requirements for growing WISPs.
Scrubbing services
A scrubbing provider receives your traffic (rerouted via BGP or GRE during an attack), discards the malicious flows and forwards the clean remainder. More surgical than blackholing, at higher cost and with some added latency while diversion is active. Evaluate providers on scrubbing capacity, time-to-mitigate, and whether activation is automatic or a phone call at 2 a.m.
DIA and transit with built-in protection
Some dedicated Internet and IP transit products include always-on or on-demand DDoS mitigation. Ask specifically what is included, at what attack volume it engages, and whether mitigation is automated — "we'll do our best" is not a mitigation SLA. SmashByte sources and compares these options across providers when you request WISP network pricing.
Architecture: making attacks expensive instead of fatal
Design choices made long before any attack determine how much damage one can do.
- Headroom on backhaul. Running circuits near saturation during normal peaks means a small flood becomes an outage. Headroom buys time for mitigation to engage.
- Diverse paths. Redundant backhaul over physically diverse routes gives you somewhere to move traffic and a way to keep management access alive while a primary path is being scrubbed. Failover mechanics are covered in route failover between two providers.
- Aggregation upstream of towers. Filtering at one or two aggregation routers protects many towers at once and gives you bigger, more capable hardware at the point where floods arrive.
- Segmentation per tower. Routable separation between towers confines blast radius — an attack on one site's subscribers should not degrade another site's.
- Offload what you can. Customer-facing DNS, portals and voice services hosted behind anycast or CDN-style absorption infrastructure are far harder to knock over than the same services on a single server behind a single circuit.
Detection and response: the runbook matters more than the tool
Most tower outages from DDoS are extended not by the attack but by slow, improvised response. A minimal working setup:
- Flow visibility. NetFlow, sFlow or IPFIX exported from aggregation and tower routers to a collector, so you can answer "what traffic, to whom, from where" in minutes instead of guessing.
- Alerts on the right signals. Interface utilization, CPU, connection-table usage and per-prefix traffic anomalies — tuned so alerts are rare enough to be trusted.
- A written escalation path. Who has authority to blackhole a prefix, the provider's NOC contact and your account identifiers, the scrubbing activation procedure, and a subscriber communication template.
- Post-incident review. Every attack that caused pain gets a short write-up: what saturated, how long detection took, and one concrete fix. Repeat incidents should get cheaper each time.
If you want an objective read on how your current posture stacks up, the security score calculator is a quick self-assessment across the domains that matter for a network operator.
Mitigation options compared
| Layer | Stops | Limitations | Cost profile |
|---|---|---|---|
| On-tower ACLs, CoPP, rate limits | Small protocol attacks, management-plane abuse, misbehaving subscribers | Cannot help once backhaul is full | Configuration time only |
| Upstream RTBH (blackhole) | Volumetric floods aimed at specific prefixes | Targeted addresses go offline; needs provider support and BGP | Usually included with transit |
| On-demand scrubbing | Large volumetric and mixed attacks, target stays reachable | Activation delay, added latency during diversion | Per-incident or retainer |
| Always-on protected DIA/transit | Continuous automatic mitigation at the provider edge | Coverage caps vary widely; read the fine print | Built into circuit pricing |
| Architecture (headroom, diversity, segmentation) | Blast radius; buys time for everything above | Not a substitute for active mitigation | Design and circuit investment |
DDoS readiness checklist
| Item | Done? |
|---|---|
| Management plane unreachable from subscriber and public space | ☐ |
| CoPP / control-plane rate limits on tower and aggregation routers | ☐ |
| Egress anti-spoofing filters on all subscriber-facing edges | ☐ |
| Recursive DNS locked to your own subscribers | ☐ |
| Flow export (NetFlow/sFlow) collecting from aggregation points | ☐ |
| Blackhole community support confirmed with each upstream provider | ☐ |
| Scrubbing or protected-transit option evaluated and documented | ☐ |
| Written incident runbook with provider contacts, tested within the last year | ☐ |
Bottom line
DDoS resilience for tower infrastructure is mostly unglamorous: hardened management planes, filtering discipline, headroom, diverse paths, and an upstream provider whose mitigation capabilities you verified before signing. The operators who weather attacks well are not running exotic gear — they did the basics in advance and wrote down the escalation path.
Start with the checklist above, close the gaps you control on-site, and then make upstream mitigation a buying criterion for your next backhaul or transit decision. The SmashByte Wireless team works through exactly these trade-offs with operators when sourcing connectivity.
Want an outside read on your tower security posture?
SmashByte helps WISPs assess DDoS exposure, harden tower infrastructure and source connectivity with real mitigation built in.
Request Security Assessment